Wednesday, June 26, 2013

Visual Education Statistics - Item Mark Patterns


                                                             16
The last post stated, “Lower individual PBR values result from mixing right and wrong marks in an item pattern. Wider score distributions make possible longer item mark patterns.” I was curious about just how does this happen?

I marked Item 30 in Table 19 with five locations. The top location contained four right marks (1s). This location was then changed to wrong marks (0s) and the four right marks were moved one count below. A visual education statistics engine (VESE) table was developed. This process was then repeated in each of the three lower locations.

The above process took an item with an unmixed mark pattern (14 right and 26 wrong) and mixed wrong marks into four lower locations, each with a one right count lower score. I moved four marks as it took this many to get a measurable result with all six statistics with the standard deviation (SD) set at 4 or 10% on a test with 40 students and 40 items (Chart 40).

I did the same thing with the SD set at 2 or 5% (Chart 41) where the effect on lowering the item PBR is greater. But a SD of 5% is not a realistic value. The effect of mixing right and wrong marks would be even less with the SD set at 8 or 20% with 40 students and 40 items. My assumption, at this point, is that the mixing of right and wrong marks will be of little concern in large tests such as standardized traditional multiple-choice (TMC) tests.

Chart 42 shows an interesting observation. Mixing just one count makes no change in the individual PBR for item 30. The reason for this can be seen in Table 19. When a right mark with a related student raw score of 30 is mixing with the next lower location of 29, the math is 30 -1 = 29 and 29 + 1 = 30. The student scores do not change. The students getting the scores do change.
The deeper the mixing, the further the right marks are moved down the student score scale, the lower the individual PBR. But the individual PBR increases the further an unmixed mark pattern descends or lengthens, up to a point.

Items 26 to 31 in Table 19 show how this happens. An S-shaped or sigmoid curve is etched into Table 19 with bold 1’s. Each item is less difficult as you go from item 31 to 26 (0.25 to 0.75). Each mark pattern lengthens linearly.

[The number of mark patterns was 10 at 5% student score SD and 20 at 10% student score SD.]

The PBR and individual variance increase to a point and then decrease (Chart 43). That point is the 70% average student score set for the test. The test score sets the limit for individual item PBRs. In this table, based on optimum conditions, that is 0.73 PBR which provides plenty of room for classroom tests that generally run from 0.10 to 0.50.

Item 29 shows a difficulty of 0.45 and variance of 0.25. Item 28 shows a difficulty of 0.55 and a variance also of 0.25. They fall equidistant from the item difficulty mean of 20 or 0.50. The junction of mean student score and mean item difficulty set the PBR limit.

This has practical implications. The further away the average student score is from 50%, the lower the limit on item discrimination (PBR).

In Table 19 an unmixed marking pattern can only be 12 counts long before it decreases. If the test score had been 50%, the marking pattern could have been 20 counts long and the PBR 100% (as shown in previous posts).

This all comes back to the need for discriminating items to produce efficient tests; tests using the fewest items to rank students using TMC. The problem is, we do not create discriminating items. We can create items, but it is student performance that develops their PBR. This provides useful descriptive information from classroom tests. The development of PBR values is often distorted with standardized tests under conditions that range from pure gambling to being severely stressful.

It does not have to be that way. By offering Knowledge and Judgment Scoring (KJS), or its equivalent, students can report what they actually know and can do; what they trust as the foundation for further learning and instruction. The test then reveals student quantity and quality, misconceptions, the classroom level of thinking, and teacher effectiveness; not just a ranking.

Most students can function with high quality even though the quantity can vary greatly. The quality goal of the CCSS movement can be assessed using current efficient technology once students are permitted to make an individualized, honest and fair report of their knowledge and skills using multiple-choice; just like they do on most other forms of assessment.

- - - - - - - - - - - - - - - - - - - - - 

Free software to help you and your students experience and understand how to break out of traditional-multiple choice (TMC) and into Knowledge and Judgment Scoring (KJS) (tricycle to bicycle):


Wednesday, June 19, 2013

Visual Education Statistics - Student Development


                                                             15
The visual education statistics engine (VESE) is now capable of producing a statistical signature for a course using traditional multiple-choice (TMC) and Knowledge and Judgment Scoring (KJS). 

I selected two scenarios that explore three consecutive tests in each one. All items are set for maximum discrimination (right and wrong marks are not mixed). All student score distributions are normal. Both courses start with an average score of 50% and end with an average score of 70%. A standard deviation of 10% is considered normal and convenient for setting grades.

The first scenario is a class that starts with students of relatively equal abilities (Chart 36). As the course progresses the score distribution widens. This is the natural consequence of the better students doing better and the poorer students lagging behind; a typical result when using TMC that primarily only ranks students. [A good example of how evolution actually works: the self-empowered survive.]

The second scenario is a class that starts with students spread out widely (Chart 37). As the course progresses the score distribution narrows. This is the natural consequence of good student development; one of the results from switching from TMC to KJS where students are empowered to report what they actually know and trust as the basis for further instruction and learning.

The statistical signatures I found are  Charts 38 and 39. In a traditional class the test reliability (KR20), the average item discrimination (PBR), the standard deviation (SD) and the standard error of measurement (SEM) all increased in value. The controlling factor was the spread of student scores.

The SD captures the spread of student scores. In these two scenarios the SD was set to increase or decrease with the average student score, as required by the score distributions in Charts 36 and 37. [The two signatures are not perfect continuations due to rounding errors and my inability to fit the 40 x 40 = 1600 marks under smooth normal curves.]

Individual item discrimination (PBR) is not the controlling factor as it has been set to the maximum for each item. [A visualization of individual  item PBR and  average item PBR is needed here. Lower individual PBR values result from mixing right and wrong marks in an item mark pattern. Wider score distributions (larger SDs) make possible longer item mark patterns. An item mark pattern is visualized in the next post.]

These statistical results are interesting. A traditional class ends with a test with increasing test reliability and a decreasing ability to separate student performance with the SEM. A class that ends with most students empowered (to question, to find answers, and to verify) shows low lower test reliability and an increasing ability to separate student performance with the SEM. This makes sense.

These two scenarios also shed light on teacher effectiveness. Both classes reached the traditional goal of mastery for schools designed for failure. The first, I would imagine, under the direction of traditional instruction aimed at the center of the class. The second would require either special attention to lower performing students or empowering most students to become self-correcting, high-achieving learners; the goal of the Common Core State Standards (CCSS) movement.

 - - - - - - - - - - - - - - - - - - - - - 

Free software to help you and your students experience and understand how to break out of traditional-multiple choice (TMC) and into Knowledge and Judgment Scoring (KJS) (tricycle to bicycle):


Wednesday, June 12, 2013

Visual Education Statistics - Item Number Limits


                                                              14
Adding more items with the same difficulties to a perfect world test on the VES Engine (Table 18) did not change the average student score (50%), the standard deviation (SD of 15.39%), the standard error (SE of 3.44%) or the average item discrimination (PBR of 0.30). The test reliability (KR20) improved but the standard error of measurement (SEM) made a marked improvement (Chart 35).

This makes sense. The more items on a test the greater the test reliability; the greater the test reliability, the smaller the range into which repeated student testing scores can be expected to fall. By doubling the number of items, twice, 20 to 80 items, the SEM fell from 5.39% to 2.64%. By doubling twice again to 320 items, the value again was reduced by half to 1.32%.

The common core state standards (CCSS) movement is now bringing into practice testing with an average difficulty of 50%. This optimizes test performance, but bullies students.

A class of 20 students, IMHO, can produce usable results if eight 40-item tests are used during the course. With a SEM of 1.32%, scores from the same student would only need to be 1.32% x 3 = 3.94% apart to show acceptable improvement in performance.

Testing companies can then market a single test, with a total number of items from 80 to 160, which will rank students and teachers with acceptable precision based on test scores. Each student will have to read every item on paper. Computer adaptive testing (CAT) will generally require less than that number, which means, CAT students will not take the same test.

Again testing is optimized for the testing companies who are only being required to rank students. They can calibrate items on a group of representative students. They can then present different items, but comparable only in difficulty, as equivalent items. This only makes sense if every student has the same general background and preparation and is an average student with average luck on test day. The practice reduces individuality and eliminates creativity. It does not have to be that way.

Armed with the above ability to rank students, testing companies are also marketing more tests: formative, summative, and in between “submative” (neither formative nor summative). The same items can be used on all three. The difference is that the formative process takes place in such a timely manner that the student learns (in seconds to minutes at higher levels of thinking and in minutes to days at lower levels of thinking). The summative test measures what has happened, not what is being learned at the moment.

The “submative” test falls in between as a subtest, but again measures the past. IMHO it also hints that buying such a test is better, in the short term, for school administrators, than letting a good teacher assess in a normal classroom. Relying on short term, lower level of thinking, tests that only rank students does not promote the development students need to become successful self-educable high quality achievers. (CCSS movement multiple-choice test questions may be highly contrived requiring considerable problem solving skills, but are still scored easier than a bingo operation: good luck on finding the right answer, with 1/4 free instead of 1/25 free.)

It does not have to be that way. The very same items can be scored to promote student development; function as formative experiences, and provide immediate guidance for teaching. Just because testing companies can deliver high quality rankings does not mean we should limit the return on the time and money invested (by students, teachers, and tax payers) to just ranking. This cripples schooling. The decade of NCLB experiences present the evidence here.

As suggested in the previous post, we need more than 20 test items and IMHO a test scored for what students trust they actually know and can do such as Power UP Plus by Nine-Patch Multiple-Choice,  partial-credit Rasch model by Winsteps and Amplifire by Knowledge Factor.

- - - - - - - - - - - - - - - - - - - - - 

Free software to help you and your students experience and understand how to break out of traditional-multiple choice (TMC) and into Knowledge and Judgment Scoring (KJS) (tricycle to bicycle):


[I again checked the test reliability values with the Spearman-Brown prophecy formula (Table 19). At this high end of the range, they closely matched the results from the VES Engine. The test with 20 items made four predictions that were increasingly close to the observed (x1) test reliability.]


Wednesday, June 5, 2013

Visual Education Statistics - Student Number Limits


                                                             13
Adding more tests from students with the same abilities to the VES Engine (Table 18) did not change the average student score, standard deviation (SD), test reliability (KR20 or Pearson r), standard error of measurement (SEM) or average item discrimination (PBR). It does change the stability of the data. A rule of thumb is that data become reasonably stable when the count reaches 300.

Above 300 the count becomes representative of what can be expected if all possible students were tested. But no student or class wants to be representative. All want to be above average. All want their best luck on test day when using traditional multiple-choice (TMC).

Although individual students do not benefit from testing increasing numbers; teachers, schools, and test makers do. The SD divided by the square root of the number of tests yields the standard error of the test score mean (SE).

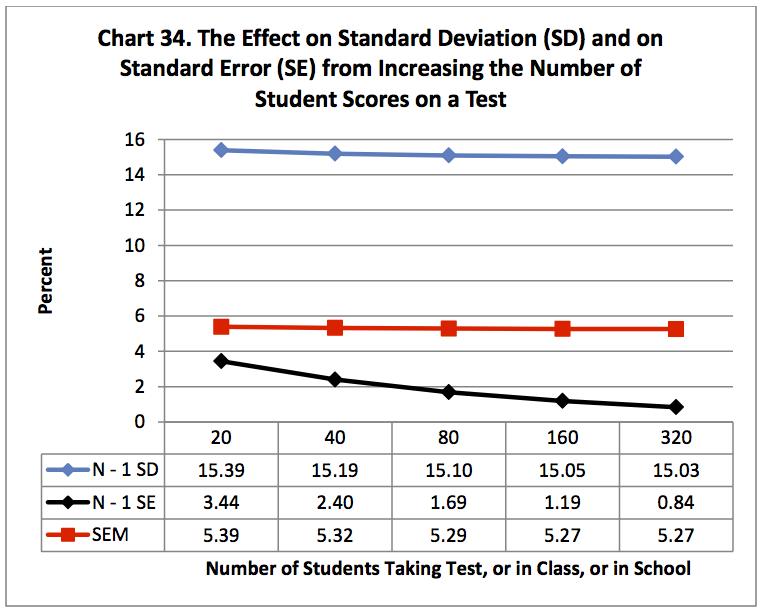
Chart 34 shows a slight curve for SD and SEM. This comes from dividing by N – 1 rather than N. The effect disappears above a count over 100. The SE is smaller than the SD and SEM and shows a marked change for the better as more tests are counted. It easily permits finding differences between groups of students when you use test enough students.

The SD, SEM and the SE have the same predictive distributions. About 2/3 of student scores are expected to fall within plus/minus one SD (15.39% for a test of 20 students) of the mean. If a student could repeat the test, with no learning from previous tests, 2/3 of the repeats would be expected to fall within plus/minus one SEM (5.39% for a test of 20 students) of the mean. These values (expected 2/3 of the time) cover too wide a range (30.78% and 10.78%) to permit separating individual student performance from year to year.

The SE is different. Starting with 20 students; SEM and SE are fairly close. But with 320 students the SE (0.84%) is five times more sensitive than the SEM (5.27%) in its ability to detect differences between groups than the SEM in its ability to detect differences in student ability.

These values are all from perfect world data (Table 18) where all students earn the same low score or high score. Item discrimination is set at the maximum. The test is performing at its best (average student score and item difficulty of 50%, test reliability at 0.877, and average item discrimination at 0.30). With only 20 items, these data indicate to me that individual student performance cannot be divided into different groupings by a perfect world SEM and therefore cannot be divided with actual classroom data either.

These data also put into question if the SE can separate group performance for individual classes, individual teachers and individual schools. The counts are just too small. Teachers with large classes, or with several sections, have an advantage over those with a small class.

Adding more students to a test is of little benefit to individual students. It is of benefit to teachers , schools, and test makers. For students we need more test items and IMHO a test scored for what students trust they actually know and can do such as Power UP Plus by Nine-Patch Multiple-Choice,  partial-credit Rasch model by Winsteps and Amplifire by Knowledge Factor.

- - - - - - - - - - - - - - - - - - - - - 

Free software to help you and your students experience and understand how to break out of traditional-multiple choice (TMC) and into Knowledge and Judgment Scoring (KJS) (tricycle to bicycle):


Wednesday, May 29, 2013

Visual Education Statistics - Lower Limits


                                                              12
I discussed the relationships between statistics in Post 11 based on changing individual answer marks. This post will start the exploration of the limits on these statistics based on student scores and item difficulties. How much change is produced by a specific strategy?

These statistics can all be used to describe what has happened in meaningful useful ways.  Here I begin to look at their ability to predict what may happen. This concern has practical value in being able to safely package descriptive and predictive statistics for maximum marketing effect. Or reworded, are testing companies really delivering what they claim?

Chart 32 relates observations from seven exploratory strategies:
  1. A perfect Guttman scaled table in a 21 by 21 cell field.
  2. A 21 by 20 Guttman table missing the item with a difficulty of zero.
  3. A 20 by 20 Guttman table also missing the student score of zero.
  4. A 20 by 20 normal curve distribution based on the SD of the above table.
  5. A 20 by 20 distribution based on a typical classroom, SD = 10.
  6. A 20 by 20 bimodal distribution at 35% and 65% student scores.
  7. A 20 by 20 perfect world distribution for the above table.

The three Guttman scaled tables produced similar results. Removing one or both zero values had little effect. The SD remained around 30% (Chart 32).

The normal curve table was also similar to the 20 by 20 Guttman scaled table but with a reduced SD (25.26%).  I was impressed that a normal curve distribution based on the 20 by 20 table SD had so little effect on the SEM and KR20. It did indicate that a shortened score range lowers the SD.

I then configured a table for a typical classroom SD. The SD = 10 table produced the smallest SEM (4.87%). SD = 9.25%. Clearly, to have a small SEM, you must have a small SD. But you also run the risk of low test reliability (0.72).

I next configured the table for a typical classroom distribution generally seen when using Knowledge and Judgment Scoring (KJS). Routine use of KJS produces and sorts out those students, who have learned to be comfortable using all levels of thinking, from the remaining passive pupils in the class who continue to select traditional multiple-choice (TMC). The bimodal table produced an SEM of 5.98%. SD = 16.38%.

I then compared a bimodal table and a perfect world table (see Post 7 in this series). In a perfect world all students receive the same low score or the same high score. These modes were set at the same 35% and 65% modes on both tables. The perfect world table (Table 18) produced similar results, SEM (5.39%). SD=15.39%.

(Free download of Table 18: http://www.nine-patch.com/download/VESEG3501.xlsm or .xls)

I explored the perfect world table further after seeing that the results for the perfect world table and the bimodal table were close at the 35%-65% mode locations. Chart 33 shows the effects of changing the range of the right and wrong modes on a perfect world table. Increasing the range increased the SEM (red) and test reliability (purple). The first effect is bad, the second effect is good. The price for a high test reliability is a reduced ability to tell if two student scores are significantly different.

Post 11 shows linear relationships when changing individual marks, except for item discrimination. This post, working with student scores and item difficulties, shows a linear relationship for item discrimination: AVG PBR of 0.1, 0.2, 0.3, 0.4 and 0.5 (Chart 33). As the two answer modes are moved farther apart, the average PBR and SD increase linearly, but appear curved on the log base 10 scale.

Standardized tests tend to have high SDs. The score distributions tend to be flat, multi-modal. This situation is related to high test reliability and high SEM (Chart 33).

A standardized test must do better than this: under the best possible conditions a SEM of about 5% is related to a test reliability of about 0.90 with the modes set at 35%-65% and a SD of 15%. That would take a difference in score from one year to the next of 3 x 5 = 15% or one and one-half letter grade to support an acceptable improvement (difference) in student performance but with an unattainable test performance.

The above tables were populated with items drawn from a Guttman scaled table with all items set at their maximum item discrimination. The results then represent the best obtainable, the maximum limit for a 20 by 20 table. We need more students and more test items.

- - - - - - - - - - - - - - - - - - - - - 

Free software to help you and your students experience and understand how to break out of traditional-multiple choice (TMC) and into Knowledge and Judgment Scoring (KJS) (tricycle to bicycle):


Wednesday, May 22, 2013

Visual Education Statistics - Basic Relationships


                                                              11
The first ten posts in this series developed a visual education statistics (VES) engine that relates six statistics on one Excel spreadsheet. This post explores their relationships by switching right and wrong marks (1 and 0) in matched pairs and in unmatched single switches at increasing distances from the diagonal equator.

A Guttman table is an extreme distribution with each student receiving a different score. Each item also has a different difficulty. Item discrimination is set at the maximum. There is only one possible distribution for this 21 student by 20 item test (Table 17). (The Excel .xlsm or .xls version is available from Table17@nine-patch.com.)

The squared student score deviations are at zero at the test score mean and at a maximum (100) at the extremes. The opposite is the case for item sums of squares (SS) with a maximum of 5.24 at the mean of 10.5 and a minimum of 0.95 at the extremes. This makes sense as there is greater variation between student score extremes and less within item difficulty extremes (Table 17).

The standard deviation (SD) of student scores decreased (6.205 to 6.050) as matched pair switching progressed from the mean to the extreme in a linear manner (Chart 28). This makes sense as the student score deviations normally increase at the extremes. Switching marks reduced these extremes.

Test reliability also fell as matched pair switching progressed from the mean to the extreme in a linear manner (Chart 29). This makes sense as the student score N MEAN SS decreased as the switching progressed from the mean to the extreme (36.381 to 34.857 or 1.524) and as the item N MEAN SS only decreased (-3.492 to -3.574 or 0.082).

The standard error of measurement (SEM) increased linearly (1.354 to 1.423) as the switching progressed from the mean to the extreme (Chart 30). This too makes sense as a decrease in test reliability is related to an increase in the SEM.

Item discrimination (KR20 and Pearson r) decreased in a non-linear manner (Chart 31) as the switching progressed from the mean to the extreme (from 0.676 to 0.637). This also makes sense as the greater the change from a perfect Guttman table, the lower the item discrimination. Switched marks that are the farthest from the diagonal equator are the most unexpected marks.

A second scan of the Guttman table with an unbalanced single switch of right and wrong produced the same relationships as the balanced switch scan. The spreadsheet (Table 16) needed to be set to three decimal spaces to capture the detail with a minimum of rounding errors (Table 17).

The VES engine is showing three linear relationships (SD, test reliability, and SEM) and one nonlinear relationship (item discrimination). Just one switch of 1 to 0 or 0 to 1 can be detected in all four statistics. I find it interesting that such detail can be captured from a 21 x 20 table.

- - - - - - - - - - - - - - - - - - - - - 

Free software to help you and your students experience and understand how to break out of traditional-multiple choice (TMC) and into Knowledge and Judgment Scoring (KJS) (tricycle to bicycle):

Wednesday, May 15, 2013

Visual Education Statistics - Visual Education Statistics Engine


                                                                    10

The Visual Education Statistics Engine (VESEngine) contains all six of the commonly used education statistics (Table 15).


The relationship between the first five seems clear. Item discrimination, the sixth statistic in the series, needs a bit more work.

The six visual education statistics in the VESEngine (Table 15):
The Visual Education Statistics Engine
1.     Count
The number of right marks for each student is listed under RT; the number of right marks for each item by RIGHT.
2.     Average
The average student score is listed under SCORE MEAN; the average of right marks for each item by MEAN.
3.     Standard Deviation
The standard deviation (SD) for student scores is listed under BETWEEN ROW OR STUDENT as N SD and N – 1 SD for large and small samples.
4.     Test Reliability
The N – 1 test reliability is listed for KR20 and Cronbach’s alpha.  The N sources for the calculation are color coded. Select an ITEM # and then click the TR Toggle button to view the effect of removing an item from the test.
5.     Standard Error of Measurement (SEM)
The SEM calculation is listed with the N – 1 sources color coded. This ends the sequence of calculations dependent upon the previous statistic.
6.     Item Discrimination
Click the Pr Toggle button to view the UNCORRECT and CORRECT N – 1 item discrimination values.

The VESEngine is now ready to explore a number of things and relationships. The goal is to make traditional multiple-choice measurements more meaningful and useful. You can start by changing single marks or pairs of marks. The engine will do the work of recalculating the entire table except for item discrimination; that requires clicking the Pr Toggle button.

I have been concerned with how the calculations were made as much as why they were being made. This series needs to end with consideration of what meaning is assigned to the calculations.  The six statistics present three different views:
Numbers You can Count (Descriptive)
COUNT and AVERAGE
A Combination of Count and Prediction
STANDARD DEVIATION OF THE MEAN

STANDARD ERROR OF MEASUREMENT
Predictive Ratios without Dimensions
TEST RELIABILITY and ITEM DISCRIMINATION

I loaded a perfect Guttman table into VESEngine and renamed it VESEngineG (Table 16).


Download free from http://www.nine-patch.com/download/VESEngine.xlsm or .xls (Table 15).
Download free from http://www.nine-patch.com/download/VESEngineG.xlsm or .xls (Table 16).


I compared the item analysis results from Nursing124 and a perfect Guttman table to get an idea of what the VESEngine could do.
Statistic
Nursing124 (22x21)
Guttman Table (21x20)
Student Scores
16.77
80%
10
50%
Test Reliability
0.29
0.95
Item Discrimination Corrected
0.09
0.52
Standard Deviation,
N – 1
2.07
9.86%
6.20
31.00%
Standard Error of Measurement
1.74
8.31%
1.35
6.77%

The data sets represent two different types of classes. The Nursing124 data are from a class preparing for state licensure exams (80% average class score). Mastery is the only level of learning that matters. The Guttman table is both theoretical and near to the design used on standardized tests (50% average score). These average scores are descriptive statistics.

The two predictive statistics, test reliability and item discrimination, values are markedly different for the two tests. The Guttman table yielded a test reliability of 0.95 that puts it into a standardized test ranking. It did this with an average item discrimination ability of only 0.52. The Nursing124 data resulted in an item discrimination ability of only 0.09. Both of these values are corrected values. The value of 0.09 is just below the limit for detecting item discrimination (0.10) and is confirmed by the ANOVA F test as just below the limit for being different from (the many classroom and testing aspects of) chance. This makes sense.

[Power Up Plus (PUP) printed out a value of 0.26 for the average item discrimination. This in the uncorrected value for the Nursing123 data. This is the only error I found in PUP: The average item discrimination was not updated when the routine for correcting the item discrimination was added.]

The Nursing124 data Standard Deviation (2.07 or 9.86%) is much smaller than the SD (6.20 or 31.00%) for the Guttman table. This makes sense. The mastery data have a much smaller range than the Guttman table data. What is most interesting is that in spite of the larger SD range for the Guttman table data, it resulted in a smaller SEM (1.35 or 6.77%) than the Nursing123 mastery data (1.74 or 8.31%). 

Even though the Guttman table data have a SD 3 times that of the Nursing124 data, by having an item discrimination over 5 times the Nursing124 data, they produced a Standard Error of Measurement a bit less than the Nursing124 data. This interaction makes more sense when visualized (Chart 26). The similarity of the SEMs indicates that widely differing tests can yield comparable results. 

Item discrimination has been improved over the years. With paper
and pencil, the Pearson r was difficult enough. Computers enable calculations that remove the right mark on the item in hand from the related student score before calculating each item’s discrimination ability. No correction is needed. The difference in uncorrected past and corrected current results is striking (Chart 27). Also see the previous post on item discrimination.

The literature often mentions that the best standardized test is one with many items near the cut score in difficulty and with a few widely scattered in difficulty. At this time I can see that the widely scattered items are needed to produce the desired range of scores. Many items near the cut score produce a lower SD and a lower SEM. You can use the VESEngine to explore different distributions of item difficulty and student ability.

Is there an optimum relationship in an imperfect world? Or will the safe way to proceed with standardized tests remain: 1. Administer the test; 2. View the preliminary results; and 3. Adjust to the desired final result? IMHO, this method does in no way reduce the importance of highly skilled test makers working from predictions based on field tests or trial items included in operational tests.

Download free from http://www.nine-patch.com/download/VESEngine.xlsm or .xls (Table 15).
Download free from http://www.nine-patch.com/download/VESEngineG.xlsm or .xls (Table 16).

[The VESEngine has two control buttons that function independently. The Pearson r Button refreshes item discrimination. The test reliability button (TR Toggle) removes a selected item from the test and then restores it on the second click.

Set a smaller matrix by removing excess cells with Remove Contents, as shown on the perfect Guttman table (Table 16) where the most right column and lowest row have been cleared of contents. The student score mean and item difficulty mean (blue) were then reset from 22 and 21 to 21 and 20.

Create a larger matrix by inserting rows within the table (not at the top or bottom). Insert columns at column S or 19. Then drag the adjacent active cells to complete the marginal cells. Finally edit the two button TableX and TableY values in Macro1 and Macro2 to match the overall size of your table.

Please check your first results with care as I have found it very easy to confound results with typos and with unexpected changes in selected ranges, especially when copying and enlarging the VESEngine.]

- - - - - - - - - - - - - - - - - - - - - 

Free software to help you and your students experience and understand how to break out of traditional-multiple choice (TMC) and into Knowledge and Judgment Scoring (KJS) (tricycle to bicycle):